How to speed up Sphinx Real Time indexes up to 5-10 times
 Mindaugas Zukas··Updated
New type of index (Real Time) was released in Sphinx Search version 1.10.
Real Time (RT) indexes have many benefits compared to the plain indexes.
The most interesting ones are:
-
support of real time index update
-
support of MySQL protocol to manage indexes
-
support of string attributes
Sphinx Search is famous for its performance, so I decided to test search performance of RT indexes and compare it to the plain indexes.
The test server has 4Gb of RAM and 4 CPUs. I used Sphinx Search version 1.10.
The size of index data set was 1 million records. I ran 1000 queries and calculated the average response time for different configurations of the RT index and the Plain index.
The RT indexes configuration was tested with different chunk size values (this is rt_mem_limit option - RAM chunk size limit). The following configurations of RT indexes were tested:
-
rt_mem_limit = 2.5GB - blue bar
-
rt_mem_limit = 1GB - red bar
-
rt_mem_limit = 0.8GB - yellow bar
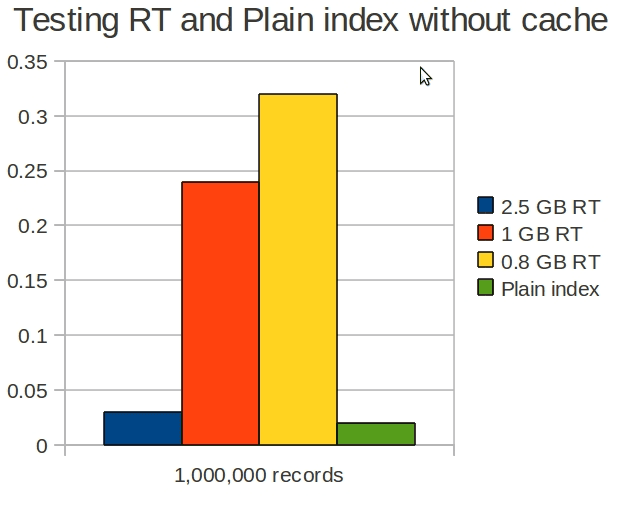
This is interestiong that the performance of 1GB and 0.8GB was very bad, but the performance of the 2.5 Gb index was quite similar to the Plain index. The reason why is because the structure of a chunk of Sphinx RT index is very similar to the structure of Sphinx plain index. In the test 2.5 GB memory was enough to fit all data in one chunk, that's why the performance of the 2.5 GB RT index was similar to the Plain index. The RT indexes with 1GB and 0.8GB have more than one chunk and this caused several times performance degradation.
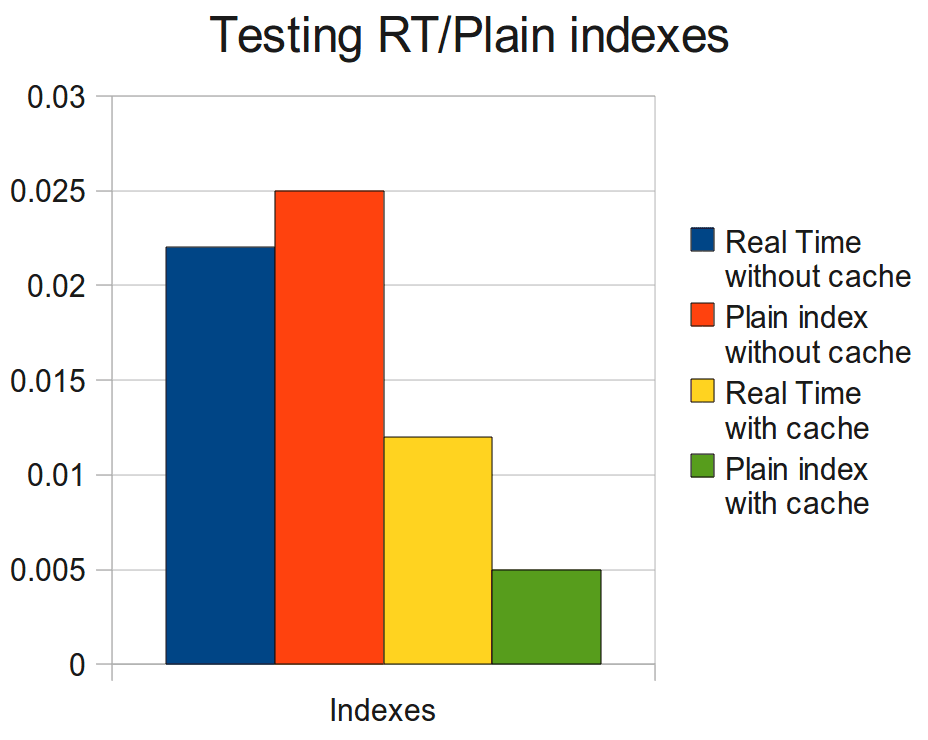
When doing my tests I noticed that the queries to the small indexes are executed faster than those to the big ones. Therefore, I decided to split my 1 million docs index into 5 RT indexes (rt_mem_limit was set to 0.7Gb) each is 200 thousands docs. Using the distributed type of Sphinx index I joined all 5 parts into one.
This time I did two tests:
-
with empty cache - it means each query to the index was the first and unique
-
with cached queries - it means that each request has already been executed once, so Sphinx/OS already has it in cache
The results are:
Results:
-
Non-cached queries against the RT index were performing a bit faster than in the Plain index (blue and red bars accordingly).
-
Cached queries against the Plain index were two times faster than against the RT index (green and yellow bars accordingly).
Conclusions:
-
If all indexed data fits into one chunk (rt_mem_limit is high enough) of Sphinx RT index, then the performance of the RT is the same as the Plain index.
-
Overall performance was improved up to 5-10 times by splitting one big RT index into 5 smaller parts.
-
Performance of RT indexes significantly depends on the number of chunks. The more chunks RT index has the slower its performance.
Need help tuning Sphinx, Manticore, or migrating to a modern search backend? See our development services.
Frequently Asked Questions
What is rt_mem_limit in Sphinx Search and how does it affect performance?
The rt_mem_limit setting controls the RAM chunk size limit for Sphinx real-time indexes. When all indexed data fits within a single RAM chunk, RT index performance matches plain index performance. When data exceeds the limit and splits into multiple chunks, performance degrades significantly — sometimes 5-10x slower. Set rt_mem_limit high enough to keep your data in one chunk, or split large datasets across multiple smaller RT indexes joined via a distributed index.
How do I split a large Sphinx RT index for better performance?
Divide your data across multiple RT indexes, each small enough to fit in a single RAM chunk, then combine them using Sphinx's distributed index type. In the test above, a 1 million document index split into 5 RT indexes of 200K documents each — with rt_mem_limit set so each fits in one chunk — performed up to 5-10x faster than a single RT index with multiple chunks. The distributed index queries all parts in parallel and merges results transparently.
Should I use Sphinx RT indexes or plain indexes?
Use RT indexes when you need real-time updates, MySQL protocol support, or string attributes. Use plain indexes when data changes infrequently and you can rebuild the full index periodically. RT indexes with a single chunk perform identically to plain indexes. If your dataset is large and you need real-time updates, split across multiple smaller RT indexes to maintain performance comparable to plain indexes.
Related Reading
Related posts
Massive Indexing with Sphinx
Imagine the following situation: multiple Sphinx daemons are serving huge amount of data running on numerous hardware servers.
Sphinx: building 1M docs index having no one real doc
Just want to share an interesting trick on how to easily index something with Sphinx without need of populating database with a lot of data or doing smth...
Correct ordering of search result set using Sphinx
**Once you get results from Sphinx, it is important to maintain the way they are ordered. The typical search process used by Sphinx looks like the following:**