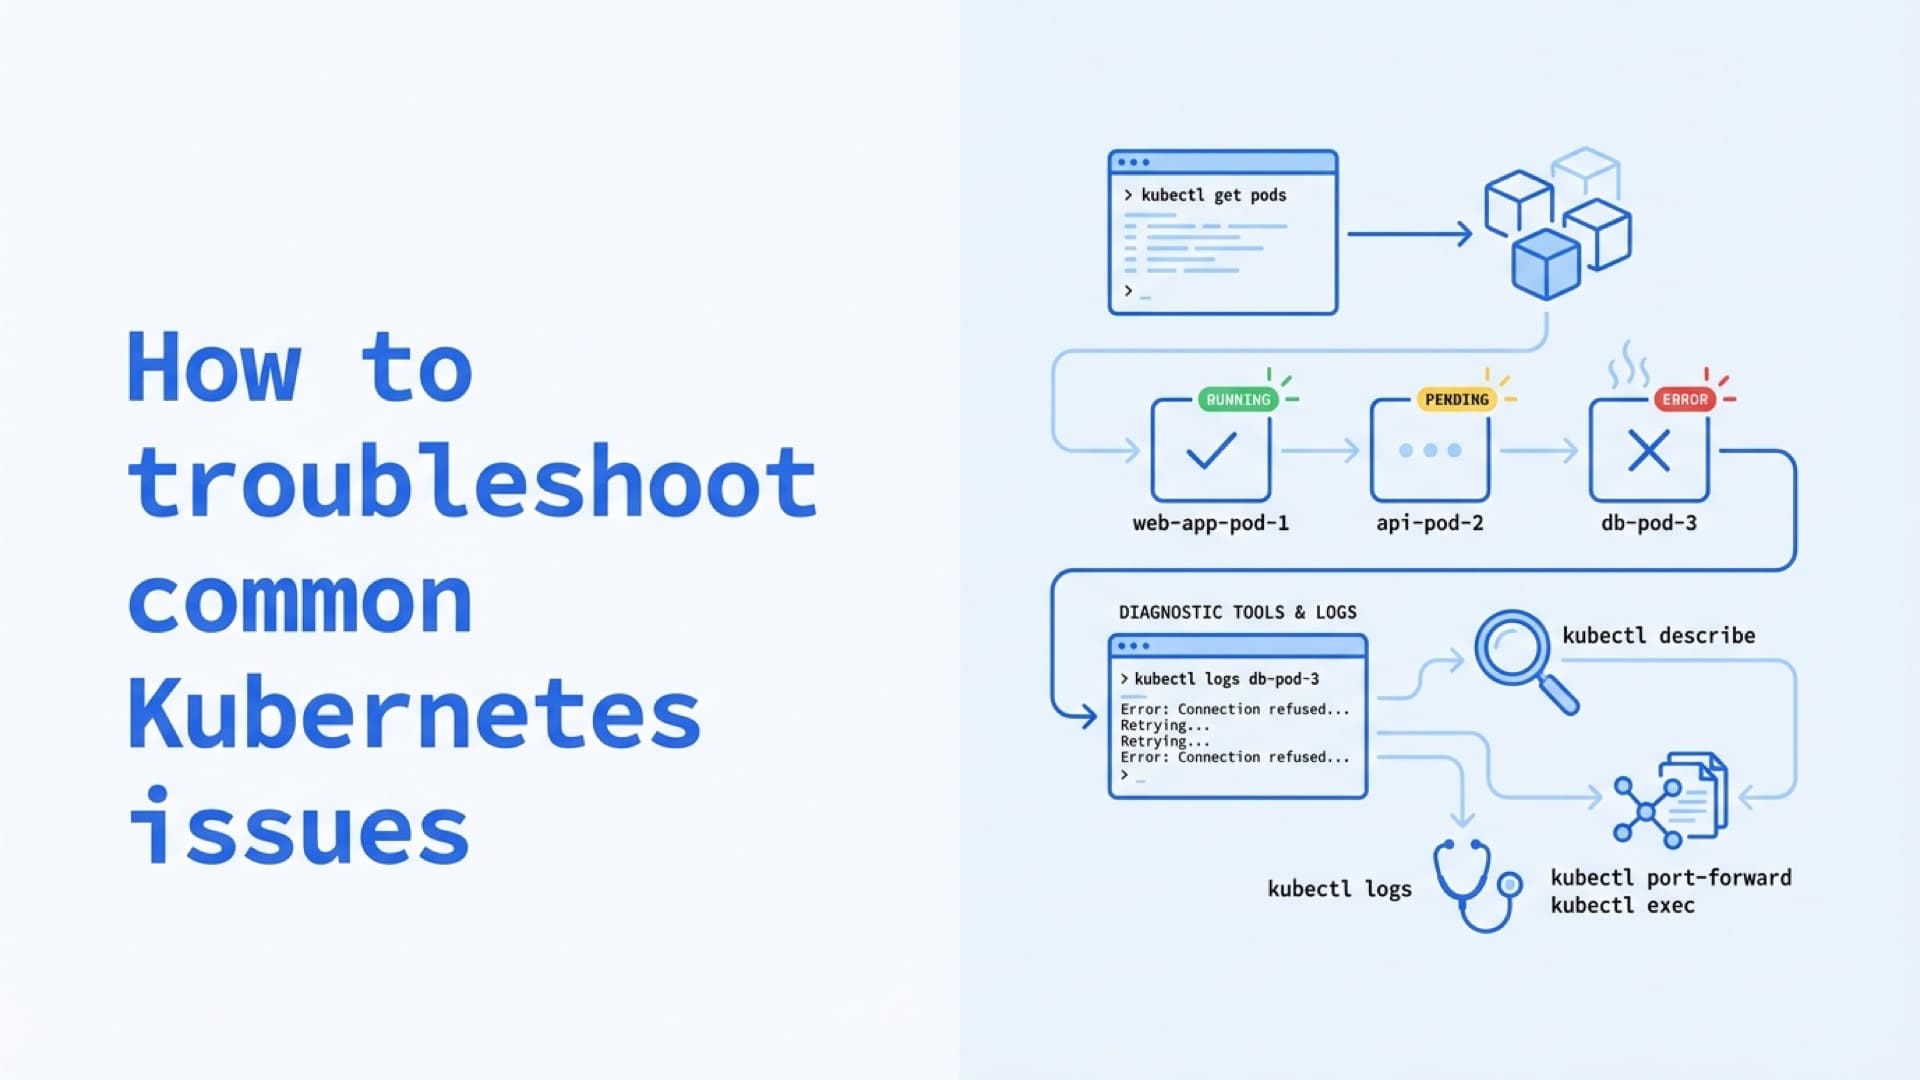
How to troubleshoot common Kubernetes issues
 Mykhailo Liepieshko··Updated
Kubernetes is a popular open-source platform for managing containerized workloads and services. It provides the flexibility to scale and distribute applications quickly and efficiently. However, it's not without its challenges, and users often run into some common issues. This article will guide you through how to troubleshoot common Kubernetes issues, from understanding error messages to resolving typical problems.
1. Pods Are Not Starting or Are in a CrashLoopBackOff Status
If your pods are not starting or keep restarting, it can be due to a variety of reasons:
-
Insufficient resources: If the node doesn't have enough resources (CPU or memory), the pods may not start. You can review the resource requests and limits for your pods and adjust them if necessary.
-
Errors in your application: If there's an issue with your application code, Kubernetes will try to restart the pod in a cycle, leading to a CrashLoopBackOff status. Checking the logs of the problematic pod can provide valuable insights into what might be going wrong. You can use
kubectl logs <pod-name>to access the logs. -
Liveness and readiness probes: If improperly configured, these can cause a pod to restart or never reach the "ready" state. Check the configuration of your probes and adjust as needed.
For example, if you see that a pod is failing with OutOfMemory error, it means that the pod has exceeded its memory limit. You can increase the memory limit in the pod specification or optimize your application to use less memory.
As another example, if you see the CrashLoopBackOff status, your application might be crashing immediately upon start. Use the command kubectl logs <pod-name> to view the logs. For example, kubectl logs my-app-56f9f7ff58-wxk4n might reveal that your application is trying to connect to a database that doesn't exist, leading to the application crash.
For a deeper dive into application-level troubleshooting, see our guide on Kubernetes troubleshooting.
2. Services Are Not Accessible
If your services are not reachable, here are some things you should check:
-
Service configuration: Confirm that the service is correctly configured to route traffic to the right pods. Use
kubectl describe service <service-name>to get the details of your service. -
Networking and firewall rules: Ensure that there are no network policies or firewall rules preventing access to your services.
-
Ingress controller: If you're using an ingress controller to manage access to your services, confirm that it's correctly configured and working as expected.
An example of a service not being accessible might be when you attempt to hit the service endpoint, but receive a 404 Not Found error. This may be because the service is not correctly routing traffic to your pods. Use kubectl describe service my-service to check the service configuration.
If you're using an ingress controller like Nginx or Traefik, and you find your service inaccessible, verify the ingress configuration using kubectl get ingress my-ingress -o yaml. You might find, for example, that your rules are incorrectly defined, routing traffic to the wrong service. Our Ingress troubleshooting checklist covers 404, 503 and TLS errors.
3. High Resource Usage
If you notice that your nodes or pods are using more resources than expected, consider the following:
-
Optimize your application: High resource usage can often be a sign of inefficiency in your application. Consider ways you could optimize your code to use resources more efficiently.
-
Adjust resource limits: If your application legitimately needs more resources, you may need to adjust the resource requests and limits in your pod specifications.
-
Autoscaling: Kubernetes has built-in features like the Horizontal Pod Autoscaler and the Cluster Autoscaler that can adjust the number of pods or nodes based on resource usage.
For example, you might notice that your pod is consistently using close to 100% of its CPU limit. This could be an indication that your application is stuck in an infinite loop, or it may simply be that your CPU limit is too low. Use kubectl top pod my-pod to view the CPU usage.
If you see that your nodes are running low on memory, this could be due to pods using more memory than they requested. In this case, you can use kubectl describe node my-node to see which pods are using the most memory.
4. Nodes Are Not Ready or Unreachable
If one or more of your nodes are not ready or unreachable, the following could be the problem:
-
Network issues: Check if there's a problem with your network that could be preventing communication with the node.
-
Node resources: The node might be low on resources like CPU or memory. Use
kubectl describe node <node-name>to view resource usage. -
Kubelet issues: The kubelet, which is the primary node agent, might be malfunctioning. Check the kubelet logs for any signs of issues.
An example of a node issue might be when you see the status NotReady for a node when running kubectl get nodes. Use kubectl describe node my-node to view more details about the node status. This might reveal, for example, that the kubelet has been unable to communicate with the API server.
If you notice that one of your nodes is not appearing in the kubectl get nodes output at all, this could indicate a network issue. You might need to check your network configuration or contact your cloud provider for assistance.
5. Upgrading Issues
Sometimes, you might run into problems when trying to upgrade your Kubernetes cluster:
-
Version compatibility: Always check the Kubernetes version compatibility matrix before performing an upgrade.
-
Deprecation warnings: Kubernetes sometimes deprecates certain APIs or features. Check for any deprecation warnings when upgrading and address them.
-
Backup: Always back up your etcd data before an upgrade. If anything goes wrong, you can restore from the backup.
For instance, you might upgrade your cluster and find that some of your applications stop working. This could be because those applications were using a deprecated API version that has been removed in the new Kubernetes version. Always check the Kubernetes deprecation guide before upgrading.
If you upgrade your cluster and it becomes unstable or completely non-functional, this could be due to an issue during the upgrade process. This is why it's crucial to always back up your etcd data before an upgrade. For example, you can use etcd's built-in backup tools to create a backup.
Troubleshooting Kubernetes issues can seem daunting, but by systematically working through the possible causes, you can find and fix the root of the problem. Remember to make full use of Kubernetes' robust logging, monitoring, and diagnostic tools — kubectl describe, kubectl logs, and kubectl top will solve the majority of everyday issues.
Need help diagnosing persistent Kubernetes issues? Our Kubernetes team provides 24/7 incident response and root-cause analysis for production clusters.
Frequently Asked Questions
How do I fix a CrashLoopBackOff in Kubernetes?
CrashLoopBackOff means your container is starting and immediately crashing in a loop. Run kubectl logs <pod-name> to check application errors, then kubectl describe pod <pod-name> to review events. Common causes include missing environment variables, failed database connections, incorrect container commands, and out-of-memory kills. Fix the root cause in your deployment spec or application code — increasing restart delays only masks the problem.
What causes Kubernetes nodes to show NotReady status?
A NotReady node typically means the kubelet cannot communicate with the API server. Check kubelet logs on the node with journalctl -u kubelet, verify network connectivity, and review resource pressure with kubectl describe node <node-name>. Common triggers include disk pressure, memory exhaustion, expired certificates, and network partition between the node and the control plane.
How do I troubleshoot Kubernetes service connectivity issues?
Start by confirming the service endpoints exist with kubectl get endpoints <service-name>. If endpoints are empty, your label selectors don't match any running pods. Next, test DNS resolution from inside a pod using nslookup <service-name>. Check network policies that might block traffic, verify the target port matches what your container actually listens on, and ensure your ingress controller is correctly configured if using external access.
Why are my Kubernetes pods stuck in Pending state?
Pods stay Pending when the scheduler cannot find a suitable node. Run kubectl describe pod <pod-name> and check the Events section. Common causes include insufficient CPU or memory on available nodes, unsatisfiable node selectors or affinity rules, PersistentVolumeClaim binding failures, and resource quotas blocking the namespace. Either scale your cluster, adjust resource requests, or fix the scheduling constraints.
Related Reading
Related posts
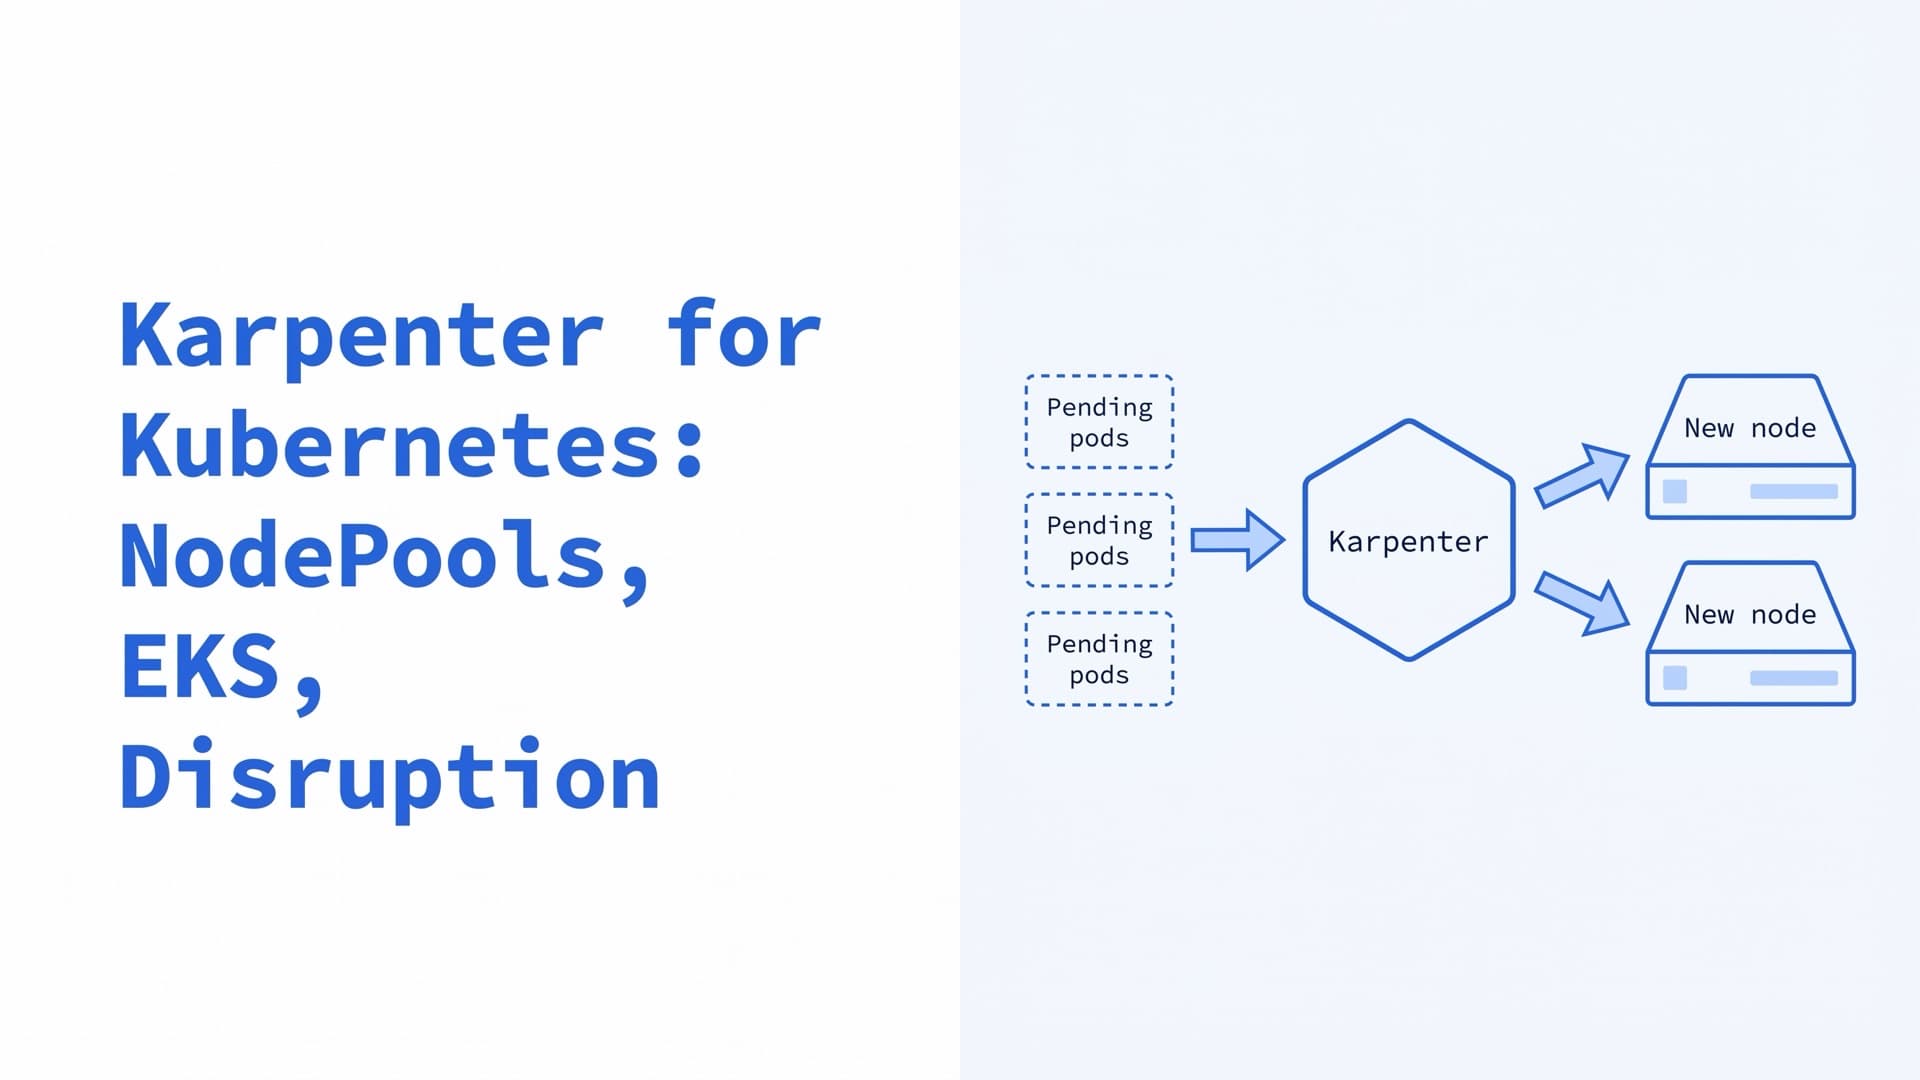
Karpenter for Kubernetes: NodePools, EKS, Disruption
How Karpenter scales Kubernetes nodes in 2026: NodePool and EC2NodeClass YAML, EKS install, Auto Mode, disruption, Cluster Autoscaler migration and fixes.
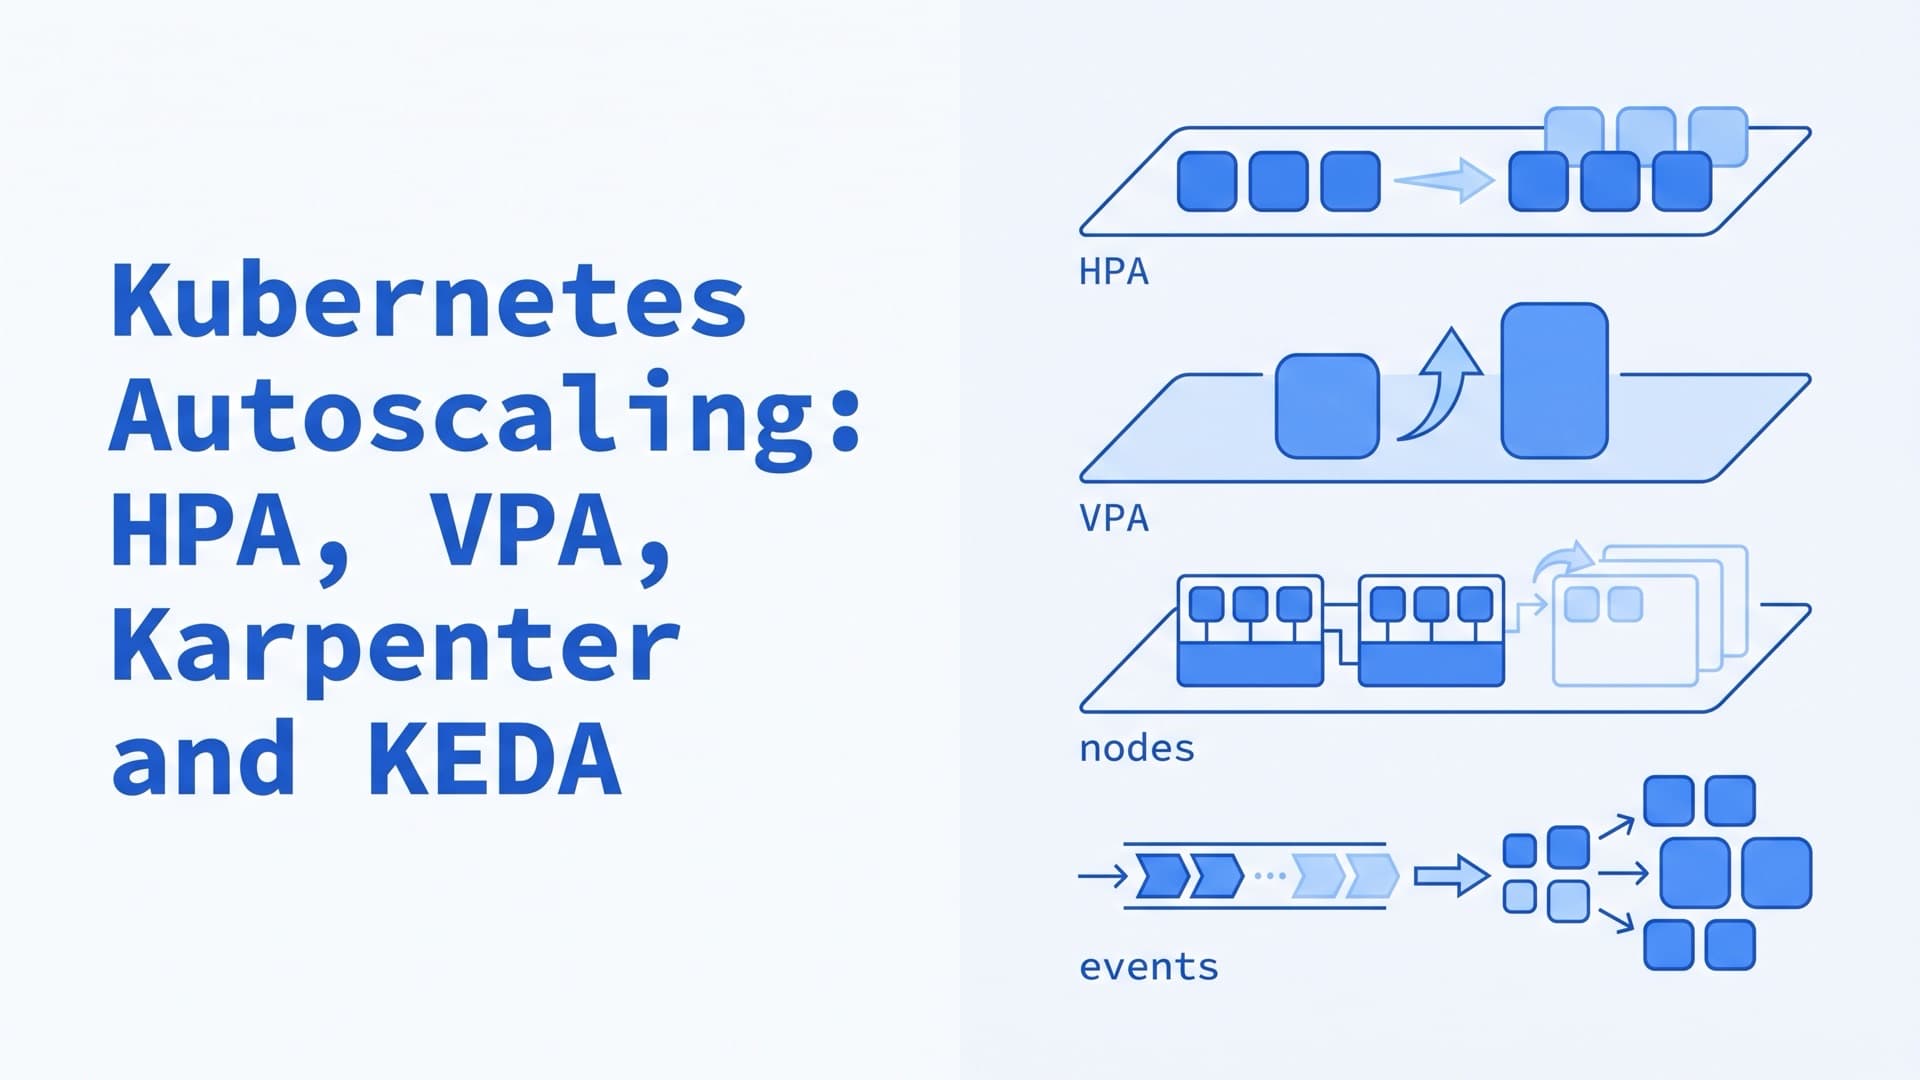
Kubernetes Autoscaling: HPA, VPA, Karpenter and KEDA
How Kubernetes autoscaling works in 2026: HPA and scale to zero, VPA in-place resize, Cluster Autoscaler, Karpenter, KEDA, YAML examples and fixes.
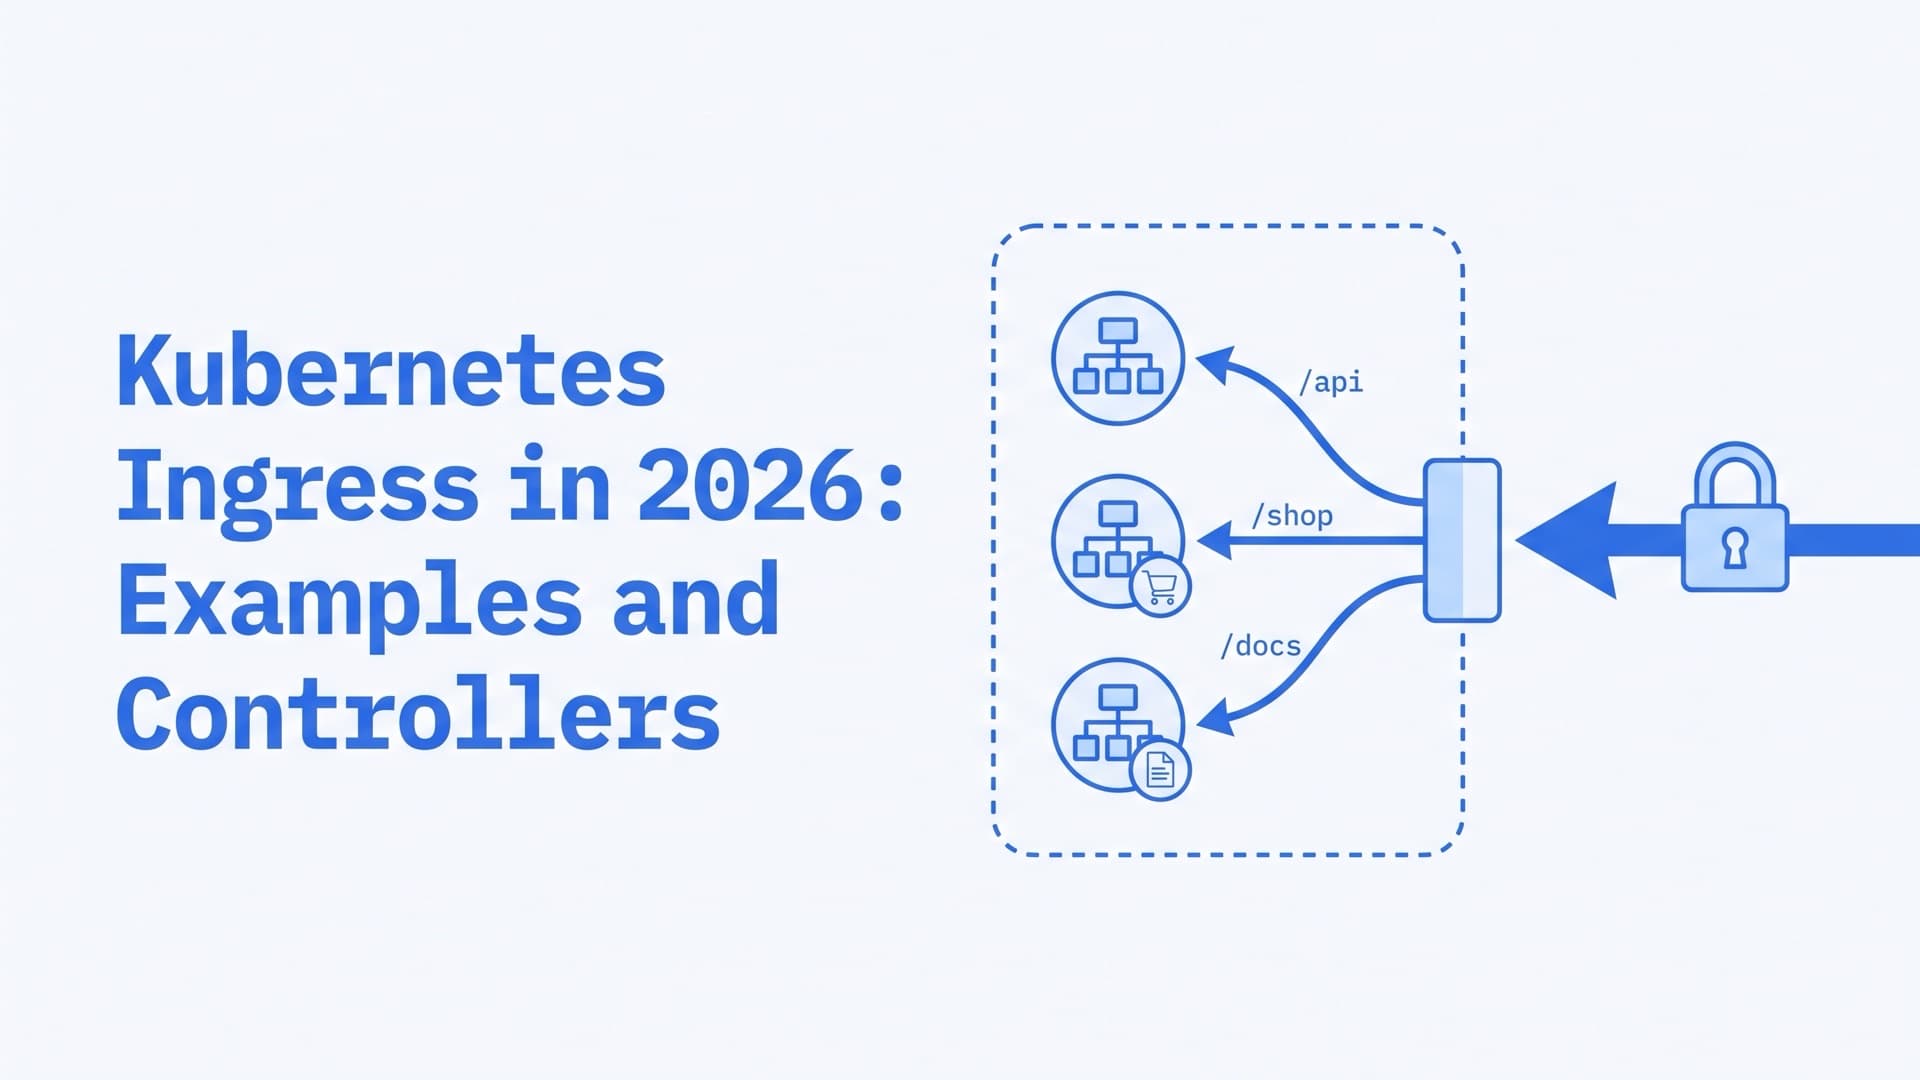
Kubernetes Ingress in 2026: Examples and Controllers
What Kubernetes Ingress is and how it works, with a YAML example, kubectl commands, controllers after ingress-nginx, Gateway API and 404 and 503 fixes.