Interesting thing about BM25 in Sphinx Search
 Mindaugas Zukas··Updated
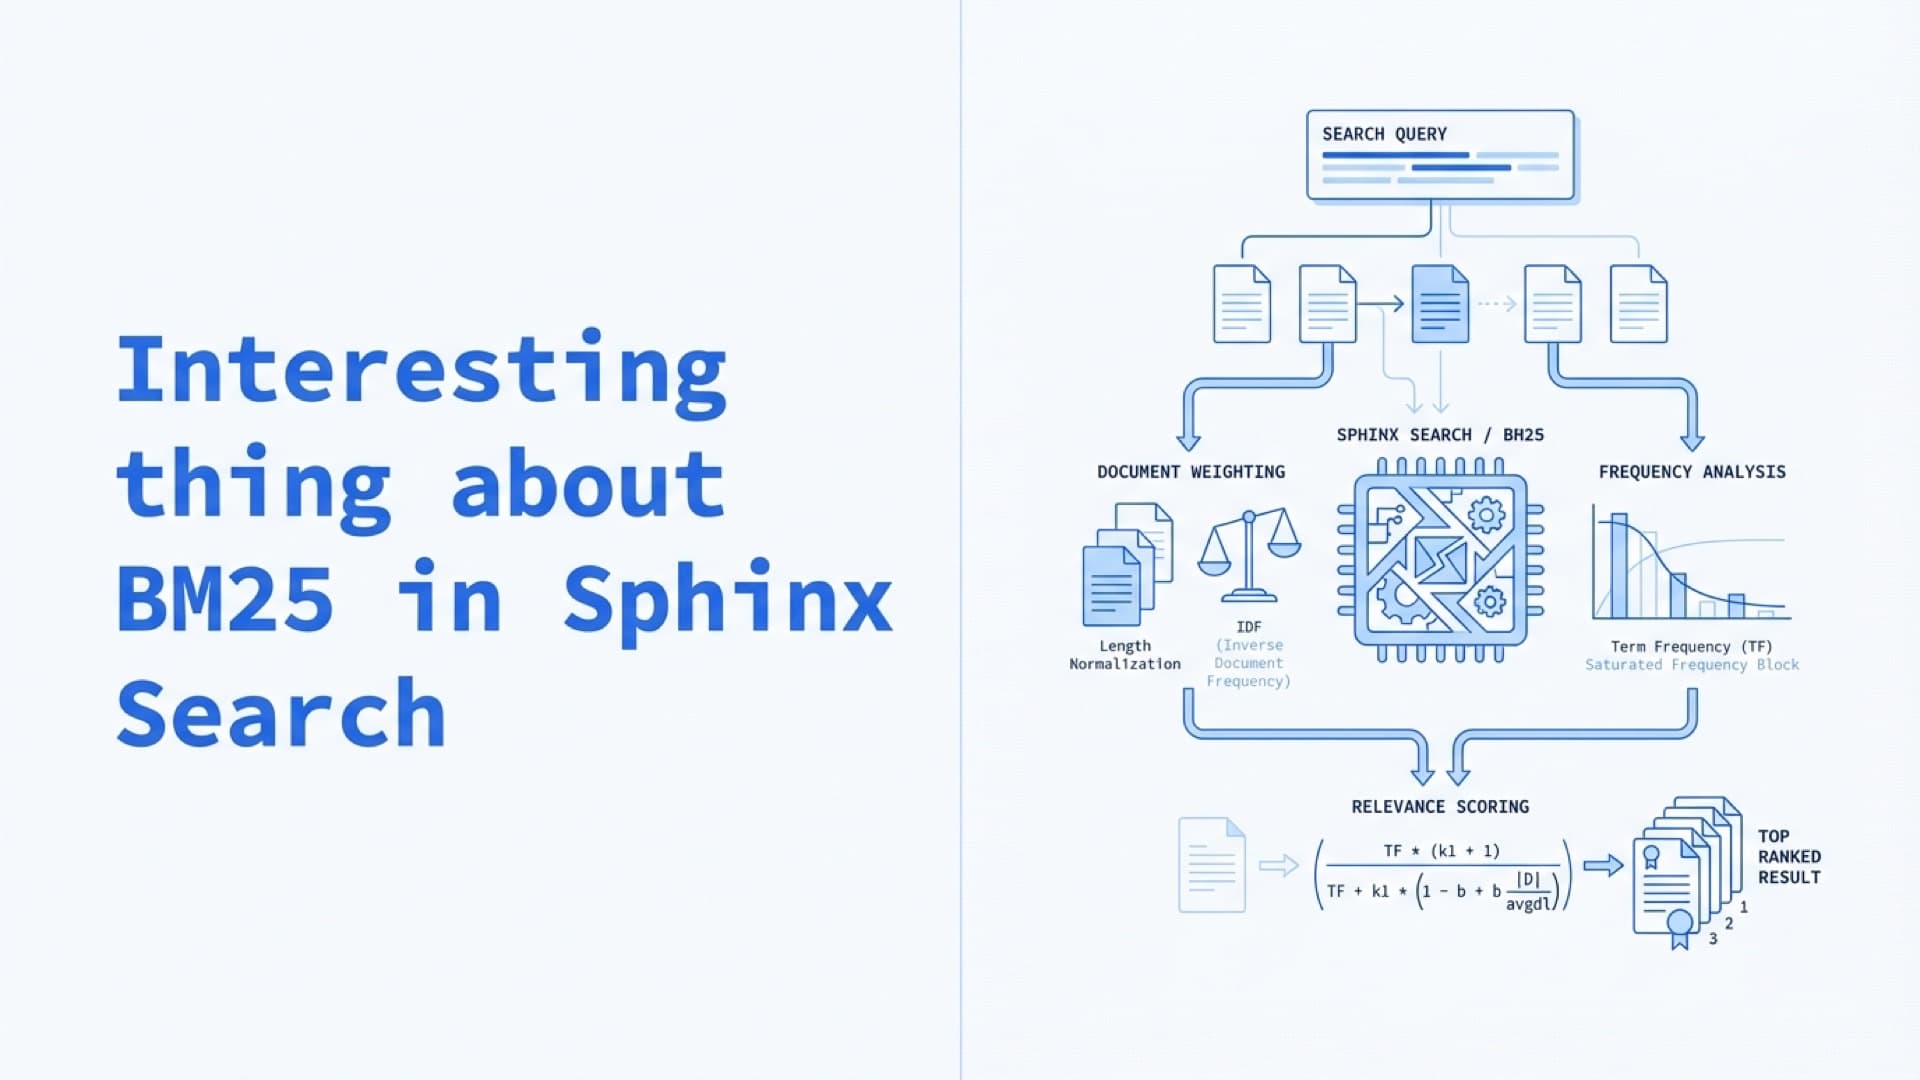
I recently faced strange behaviour of Sphinx Search. As I investigated, the problem turned out to be in the default ranking mode SPH_RANK_PROXIMITY_BM25 which is using the BM25 algorithm.
Update: according to the latest documentation SPH_RANK_SPH04 solves the problem. Anyway I suggest to read the article, it was interesting investigation.
Here's the quote from Sphinx documentation:
Statistical rank is based on classic BM25 function which only takes word frequencies into account. If the word is rare in the whole database (ie. low frequency over document collection) or mentioned a lot in specific document (ie. high frequency over matching document), it receives more weight. Final BM25 weight is a floating point number between 0 and 1.
So it states that a word which is mentioned a lot receives more weight. But it's not always true.
Let's say we have the following table with some words repeated in every row:
mysql>select * from titles;

| id | title |

| 1 | Test Category - Test Article |
| 2 | Test CategoryA |
| 3 | Test CategoryB |
Please notice that "Test" occurs two times in document #1 and only one time in documents #2 and #3.
So we can expect that a search for the word "Test" will match #1 as the first result.
Let's test it using SphinxQL (Sphinx query language):
mysql> select * from test1 where match('Test') ;

| id | weight |

| 2 | 1319 |
| 3 | 1319 |
| 1 | 1252 |
Hmm, something's wrong here, document #1 got lower weight than documents #2 and #3.
As it was investigated the key problem is that the word "Test" occurs in each document. See the quote from Andrey Aksenoff (creator of Sphinx Search):
This is actually by BM25 design. It penalizes (!) the keywords that are overly frequent, ie. occur in more than 50% of the collection documents.
In my case the word "Test" occurred in 100% of documents and that's why was penalized.
A possible workaround of this can be to use another ranking mode which doesn't use BM25, i.e. SPH_RANK_WORDCOUNT or SPH_RANK_MATCHANY:
SPH_RANK_WORDCOUNT:
mysql> select * from test1 where match('Test') option ranker=wordcount;

| id   | weight |

|    1 |      2 |
|    2 |      1 |
|    3 |      1 |
SPH_RANK_MATCHANY:
mysql> select * from test1 where match('Test') option ranker=MATCHANY;

| id   | weight |

|    1 |      1 |
|    2 |      1 |
|    3 |      1 |
It looks like SPH_RANK_WORDCOUNT solves our problem.
In some cases it can be a solution, but in general it can't, because for almost all queries we might want to use as smart ranking algorithm as default SPH_RANK_PROXIMITY_BM25 ranking mode.
Need help tuning search relevance or designing custom ranking models? See our development services.
Frequently Asked Questions
Why does BM25 penalize common words in Sphinx Search?
BM25 is designed to give higher weight to rare, distinctive terms and lower weight to common terms. When a keyword appears in more than 50% of documents in the collection, BM25 actually penalizes it — treating it as a stop word that provides little discriminative value. This is by design in the algorithm's inverse document frequency (IDF) component. In small collections where important terms appear in every document, this behavior can produce counter-intuitive ranking results.
What is SPH_RANK_SPH04 and how does it fix BM25 ranking issues?
SPH_RANK_SPH04 is a Sphinx Search ranking mode that extends PROXIMITY_BM25 with additional signals: it boosts exact field matches and gives extra weight to documents where query terms appear at the beginning of the field. This helps counteract BM25's penalization of high-frequency terms while still providing intelligent proximity-based ranking. According to Sphinx documentation, SPH04 is the recommended replacement when default BM25 ranking produces unexpected results with common terms.
How do I choose the right ranking mode in Sphinx Search?
Use SPH_RANK_PROXIMITY_BM25 (default) for most general-purpose search. Switch to SPH_RANK_SPH04 when important search terms appear frequently across your document collection. Use SPH_RANK_WORDCOUNT when you need simple term frequency ranking without IDF penalties. Use SPH_RANK_MATCHANY for boolean-style matching where any keyword match counts equally. For advanced control, use SPH_RANK_EXPR with a custom ranking expression that combines proximity, BM25, and field weights to match your specific requirements.
Related Reading
Related posts

Massive Indexing with Sphinx
Imagine the following situation: multiple Sphinx daemons are serving huge amount of data running on numerous hardware servers.

Sphinx: building 1M docs index having no one real doc
Just want to share an interesting trick on how to easily index something with Sphinx without need of populating database with a lot of data or doing smth...

Correct ordering of search result set using Sphinx
**Once you get results from Sphinx, it is important to maintain the way they are ordered. The typical search process used by Sphinx looks like the following:**