Sphinx in Action: Did you mean ... ?
 Sergey Nikolaev··Updated
This is a post from a series of posts called "Sphinx in Action". See the whole series by clicking here.
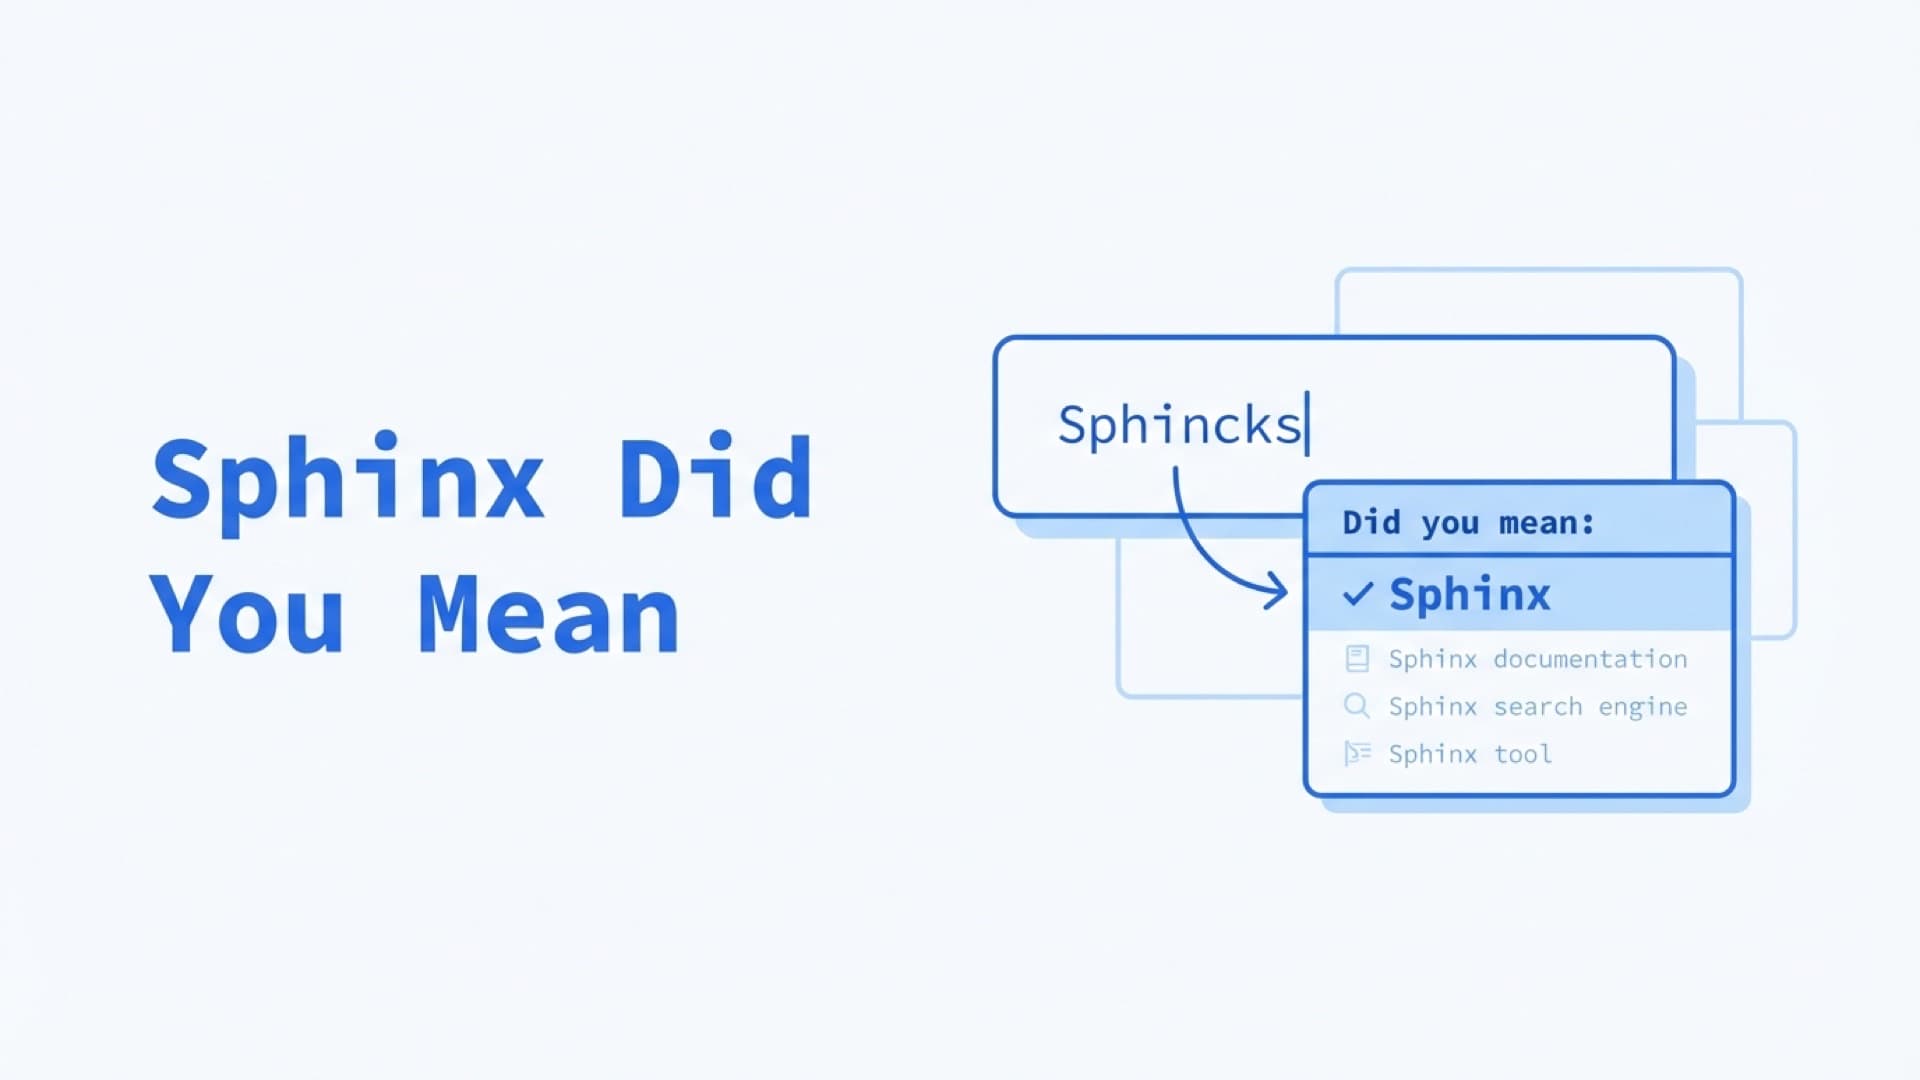
Many of our customers want to incorporate "did you mean ... ?" functionality into their applications. How it works is that when a typo is made in the query, a corrected version of the typo is suggested:
This can be done using a special technique with Sphinx that has been successfully used in many different projects.
There's a demo of this technique in misc/suggest/ dir in the Sphinx source and an article (in Russian) where Andrew Aksyonoff describes the main idea behind this. The following is based on his original idea:
The technique is based on comparing the difference between the words in the current query and words from a dictionary. How this works is:
-
You should decide what dictionary of proven words would be most suitable. It can be some real dictionary, titles of your products, or you can even generate a new dictionary based on your current index using the 'indexer --buildstops … --buildfreqs' command.
-
You can modify each word in the dictionary by splitting it into characters and groups of characters: bigrams, trigrams and so on. For example, you would convert 'mysql' to 'm y s q l m my ys sq ql l m my mys ysq sql ql l'. In this case the underscore is used to distinguish a letter in the beginning or end of the word from a letter in the middle.
-
Next, you will index your dictionary and word modifications. You can also index attributes like word length, or anything else that will help sort the results. Other examples might be: word frequency if using --buildfreqs indexer key, or product popularity rating.
-
Then you do the same with queried keywords, for example if it's 'mysslq' it becomes 'm y s s l q m my ys ss sl lq q m my mys yss ssl sly lq q', you can put letters, bigrams and trigrams into separate fields in order to improve the quality.
-
Finally, you search for the calculated string in the index using the "…"/1 syntax (i.e. the quorum operator).
The idea is that the many parts of the mistyped query will match with their respective best suggestions.
To improve quality you can use ranker=wordcount (SPH_RANK_WORDCOUNT in the API) or ranker=proximity (SPH_RANK_PROXIMITY in the API) to calculate the weight based on proximity or the number of matching words, not the statistics based BM25 algorithm.
Not only can you sort by full-text weight, but also by the difference between the mistyped query and the suggestion (the less difference the better).
You can also filter by length to avoid suggestions that are too short or too long. It is unusual that the length of a mistyped query differs much from the correct one's length (usually just 2-3 letters).
The example is:
	mysql> select keyword, len, freq, @weight + 2 - abs(7 - len) final from suggest where match('@trigrams "__m _ms mse sea eag age ge_ e__ "/1 @bigrams "_m ms se ea ag ge e_ "/1 @onegrams"m s e a g e "/1') and len >= 5 and len <= 9 order by final desc, freq desc limit 10 option ranker=wordcount;
	+-------+--------+------+------+----------+-------+
	| id | weight | freq | len | keyword | final |
	+-------+--------+------+------+----------+-------+
	| 3425  | 17 | 1560   | 7 | message | 19 |
	| 17492 | 17 | 288    | 7 | mileage | 19 |
	| 28521 | 16 | 163    | 7 | massage | 18 |
	| 10566 | 15 | 504    | 8 | messages| 16 |
	| 38476 | 14 | 114    | 7 | teenage | 16 |
	| 53885 | 14 | 74     | 7 | baggage | 16 |
	| 7198  | 13 | 755    | 7 | average | 15 |
	| 14641 | 14 | 350    | 8 | marriage| 15 |
	| 16844 | 14 | 301    | 6 | manage  | 15 |
	| 20092 | 13 | 246    | 7 | disease | 15 |
	+-------+--------+------+------+----------+-------+
	10 rows in set (0.05 sec)
To improve the quality even more, it makes sense to run additional calculations in the application AFTER you've fetched the docs from Sphinx. The simplest thing you can do is to calculate the levenshtein distance for the first ten words suggested by Sphinx.
You can also play with the weights of the fields (@letters, @bigrams, and @trigrams), the thresholds, and other attributes to find which settings will work best for your data.
Of course the suggested keywords can't be correct 100% of the time, because there are some cases when two or more suggestions are correct. It produces good results in most cases. For example, each of the following typos of the word 'message' get successfully converted to 'message' or 'messages':
essage mssage mesage mesage messge messae messag mmessage meessage messsage messsage messaage messagge messagee emssage msesage mesasge messgae messaeg nessage jessage kessage mwssage m3ssage m4ssage mrssage mfssage mdssage msssage measage mewsage meesage medsage mexsage mezsage mesaage meswage meseage mesdage mesxage meszage messqge messwge messsge messxge messzge messafe messate messaye messahe messabe messave messagw messag3 messag4 messagr messagf messagd messags nmessage mnessage jmessage mjessage kmessage mkessage mwessage mewssage m3essage me3ssage m4essage me4ssage mressage merssage mfessage mefssage mdessage medssage msessage messsage meassage mesasage mewssage meswsage meessage mesesage medssage mesdsage mexssage mesxsage mezssage meszsage mesasage messaage meswsage messwage mesesage messeage mesdsage messdage mesxsage messxage meszsage messzage messqage messaqge messwage messawge messsage messasge messxage messaxge messzage messazge messafge messagfe messatge messagte messayge messagye messahge messaghe messabge messagbe messavge messagve messagwe messagew messag3e message3 messag4e message4 messagre messager messagfe messagef messagde messaged messagse messages
Need help with search infrastructure? Talk to our engineering team — we've built and maintained search systems for over 15 years.
Frequently Asked Questions
How does "did you mean" spell correction work in Sphinx Search?
Sphinx implements spell correction by converting each dictionary word into character-level tokens — unigrams, bigrams, and trigrams. When a user submits a misspelled query, the same tokenization is applied and the result is matched against the pre-built suggestion index using the quorum operator ("/1 syntax). Rank results by proximity and word frequency, then apply Levenshtein distance post-processing to refine the top 10 suggestions.
What dictionary should I use for Sphinx spell suggestions?
Build a domain-specific dictionary from your own index using indexer --buildstops --buildfreqs. This produces a list of the words in your indexed documents, with the number of times each one occurs there, which outperforms a generic English dictionary when your content includes product names, abbreviations, or technical terms. For general sites, combining both sources improves coverage.
Which Sphinx ranker works best for spell correction quality?
Use ranker=wordcount (SPH_RANK_WORDCOUNT) for spell correction — it scores matches by the number of overlapping character n-grams rather than BM25 statistics. Pair it with an abs(expected_len - len) penalty column to penalize suggestions that differ too much in length from the original query.
Can Sphinx "did you mean" handle words with 5+ character errors?
The trigram approach degrades for very long edit distances. Filter candidates to len >= original_len - 2 AND len <= original_len + 2 to keep suggestions plausible.
How do I debug why a specific misspelling isn't being corrected?
Use CALL KEYWORDS() in SphinxQL to inspect exactly how your index tokenizes any string. This reveals which stopwords are dropped, how blend characters behave, and whether your n-gram fields contain the right tokens. Run it first, before tuning field weights or adjusting the quorum threshold.
Related Reading
Related posts
Massive Indexing with Sphinx
Imagine the following situation: multiple Sphinx daemons are serving huge amount of data running on numerous hardware servers.
Sphinx: building 1M docs index having no one real doc
Just want to share an interesting trick on how to easily index something with Sphinx without need of populating database with a lot of data or doing smth...
Correct ordering of search result set using Sphinx
**Once you get results from Sphinx, it is important to maintain the way they are ordered. The typical search process used by Sphinx looks like the following:**