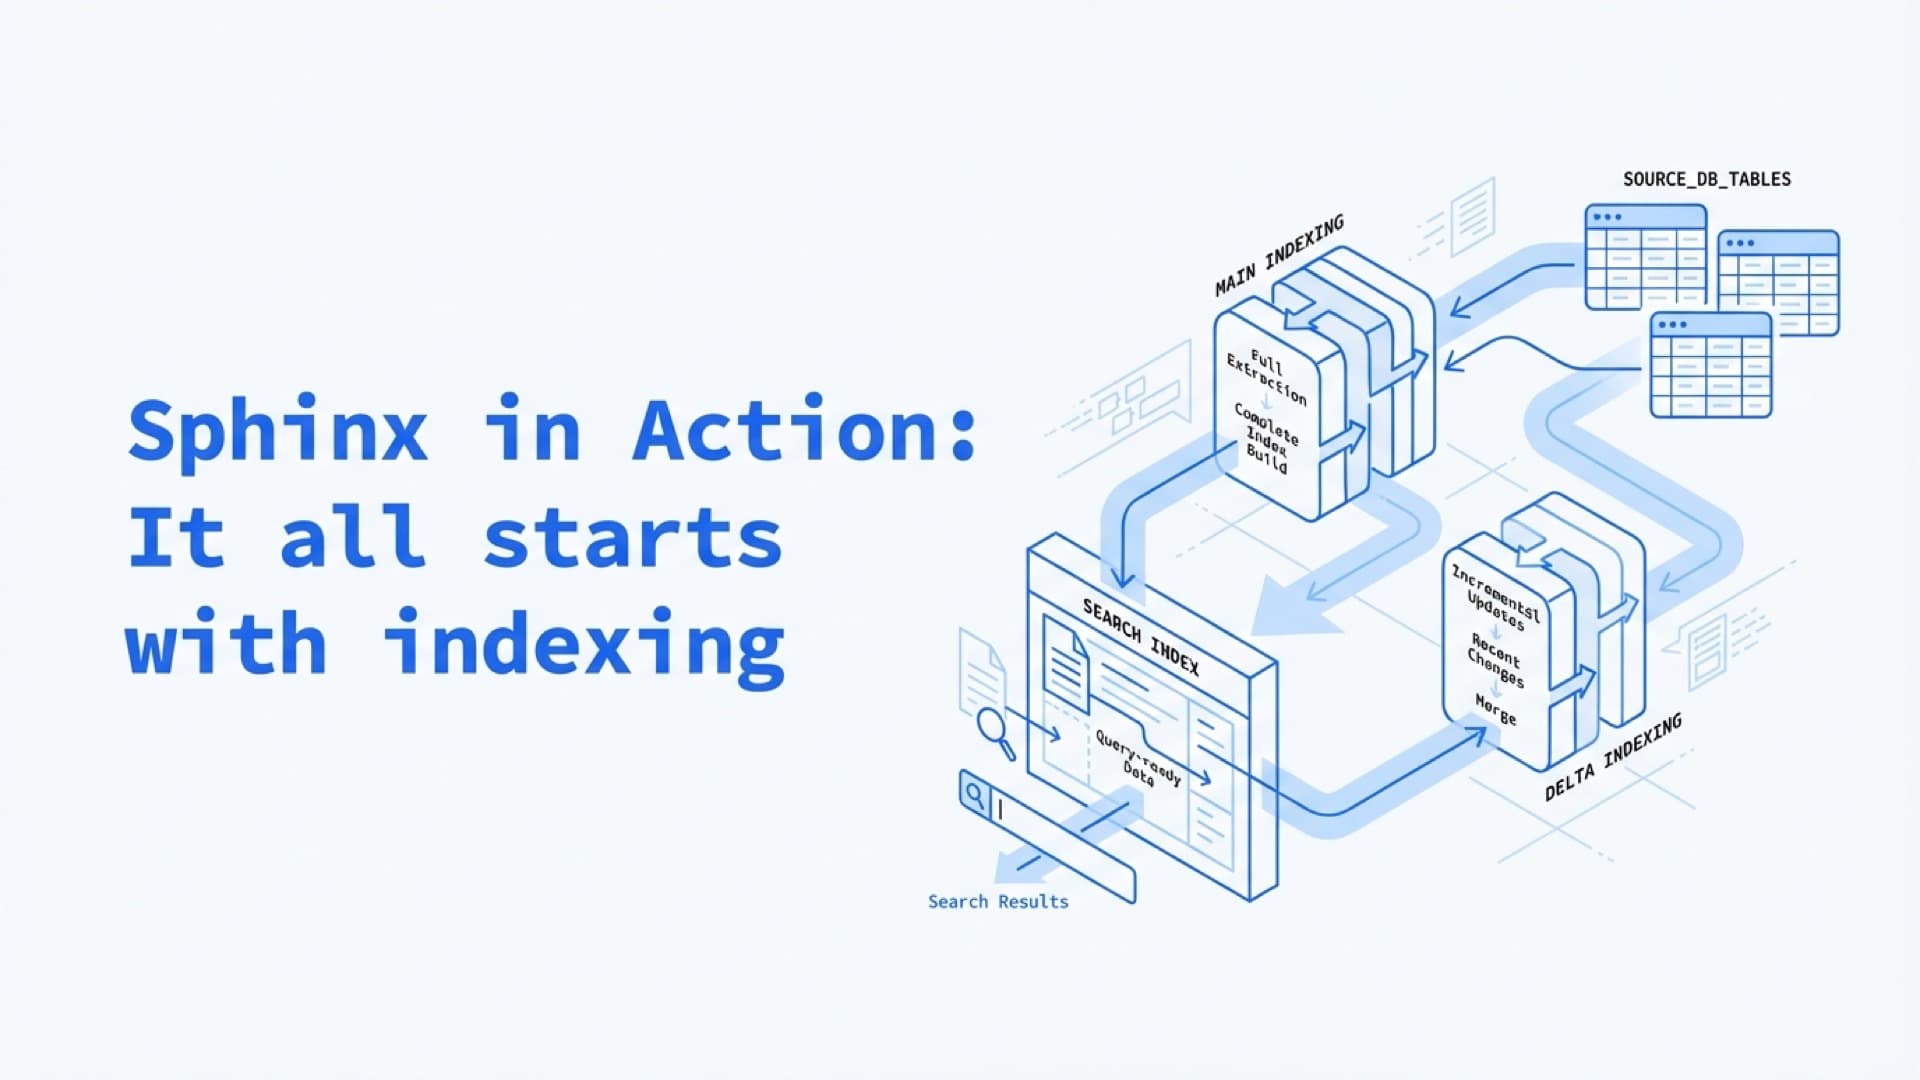
Sphinx in Action: It all starts with indexing
 Sergey Nikolaev··Updated
This is a post from a series of posts called "Sphinx in Action". See the whole series by clicking here.
Sphinx usage in any project usually starts with building the Sphinx configuration and indexing your data. In this article I'm going to point out some cool things that Sphinx provides regarding the configuration and how your data is indexed:
-
First, I have to say that it supports inheritance. This is very useful because you can define things (like the connection to your database) only once and they will be reused for all the other sources, here's an example:
-
If you're a real hater of copy-paste technology, you'll be happy to know that Sphinx config supports shebang which allows you to create your Sphinx config using your favorite scripting language, for example:
This creates many possibilities of making the Sphinx config really dynamic. It is especially important in large applications that have a lot of indexes and multiple servers. You can set up your config just once, and as you scale your project, it will rebuild itself automatically. One thing you will need to be careful is sending signal to the running searchd process so it starts using the new config. You can make life even easier by incorporating the signal sending into the config so that once you reindex, and see that the config is updated, you can inform your searchd process about this and it will switch to the new config.
Another cool thing you can do with data indexing is using a so-called main + delta scheme. Here’s what it does:
-
It reduces the frequency that the main part of the index needs to be rebuilt.
-
When you update a field in your data source and need to update this in your Sphinx index, you only need to rebuild the delta. When the delta is big enough and takes significant time to rebuild itself, you can dump all the data into the main index. This empties the delta and readies it to accept new data and start rebuilding fast again.
-
It makes your updated data appear in the index much faster.
-
By fetching less data from the database, it reduces the weight of the load on your server.
There are two main approaches when it comes to the main+delta:
-
Split data by 'id':
-
Split data by 'updated':
Need help with search infrastructure? See how Ivinco's development team can help →
Frequently Asked Questions
What is the main+delta indexing scheme in Sphinx?
Main+delta splits your index into two parts: a large, infrequently rebuilt main index and a small, frequently rebuilt delta containing only recent changes. The delta rebuilds in seconds because it processes only new or updated records. When the delta grows too large, you merge it into the main index. This pattern reduces database load and makes search data appear within minutes of changes.
How does Sphinx config inheritance work?
Sphinx supports source and index inheritance using a colon syntax: source child : parent. The child inherits all settings from the parent and can override specific ones. Use this to define database connection details once in a parent source, then create per-table child sources that only specify their sql_query. This eliminates duplication across configs with dozens of indexes.
What is the difference between splitting data by ID vs by update timestamp?
Splitting by ID uses a counter table to track the last indexed document ID — the delta processes only IDs above that counter. Splitting by update timestamp uses a last_modified column to find changed records. ID-based splitting is simpler and works for append-only data. Timestamp-based splitting catches both inserts and updates but requires every table to have a reliable timestamp column.
Related Reading
Related posts
Sphinx in Action: Fuzzy matching and 2nd pass query
This is a post from a series of posts called "Sphinx in Action".
Sphinx in Action: Top related queries
This is a post from a series of posts called "Sphinx in Action".
Sphinx in Action: Autocomplete
This is a post from a series of posts called "Sphinx in Action".