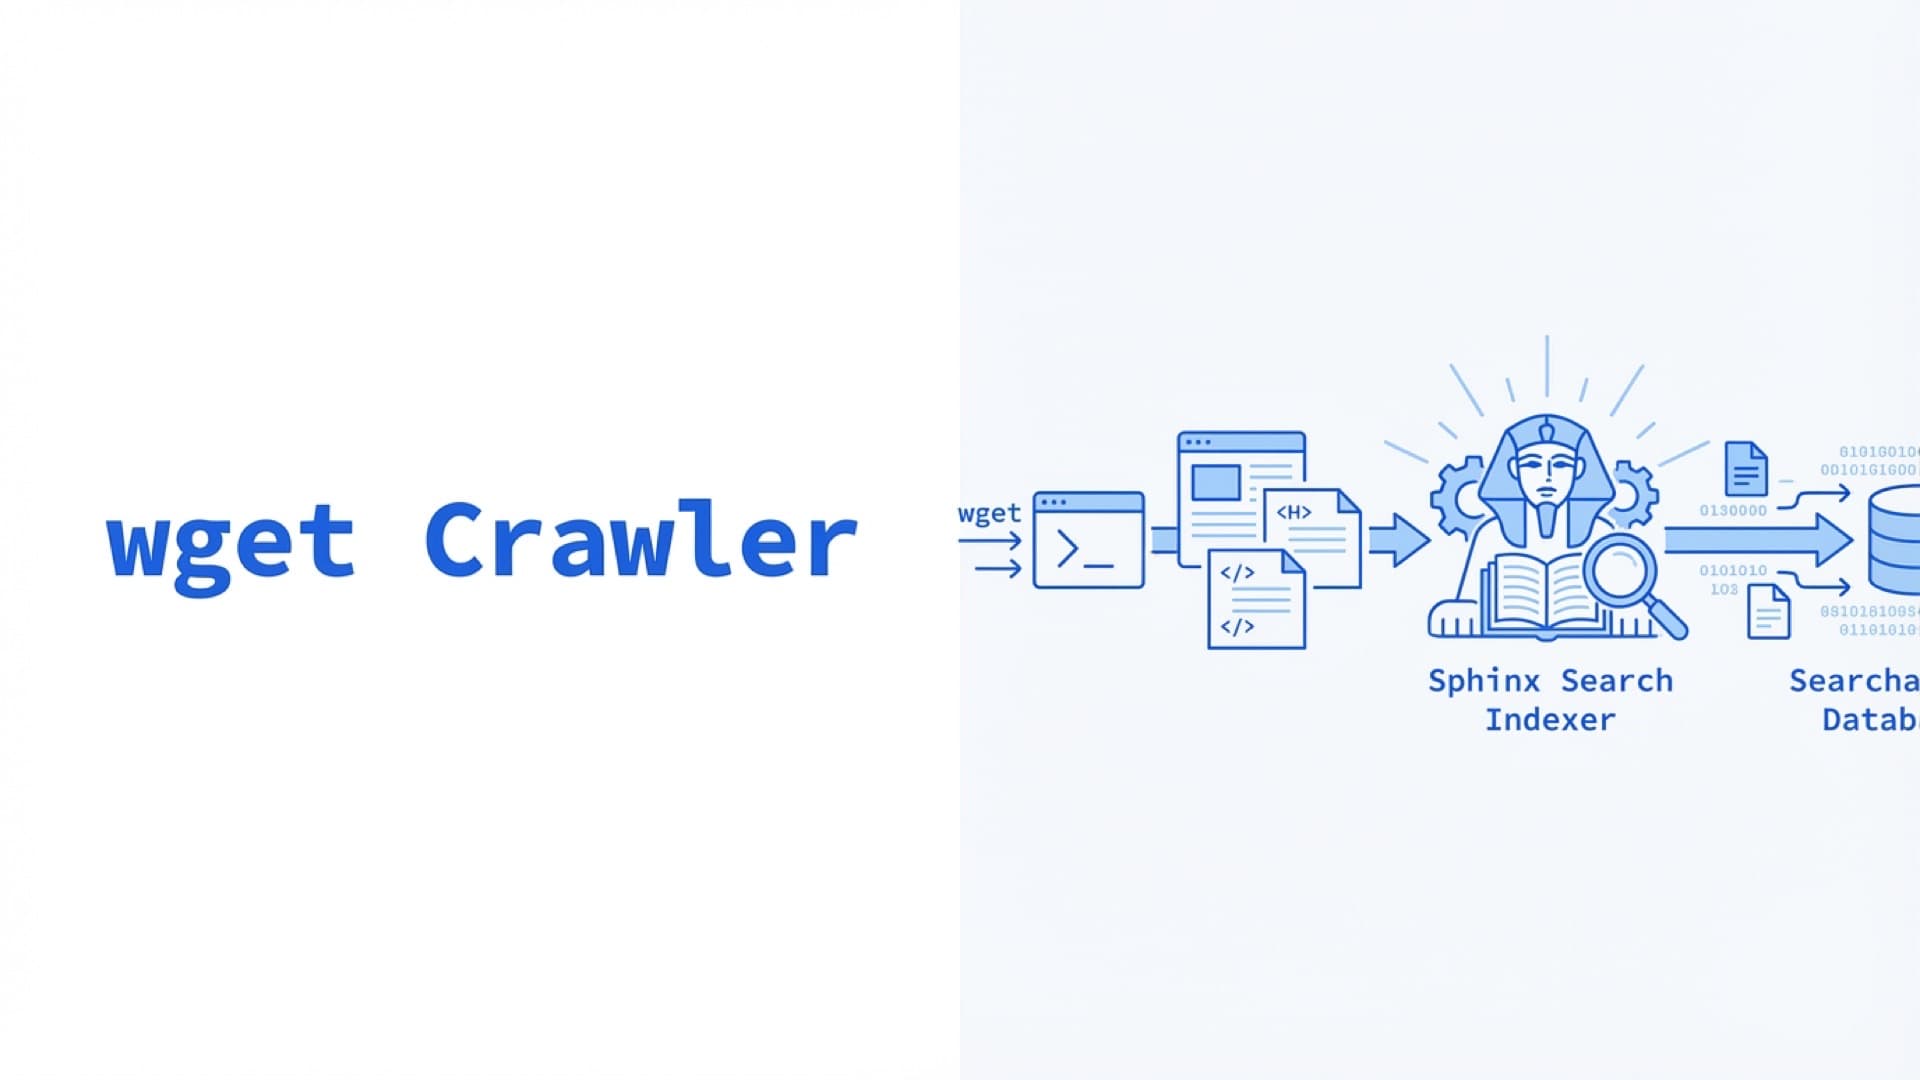
Using wget as a simple web crawler for Sphinx search engine
 Sergey Nikolaev··Updated
The following is just a proof of concept which shows that it's possible to make a search engine of a web site with minimal tools and knowledges:
-
wget
-
bash
-
Sphinx: cool directive sql_file_field is used
-
mysql
To make data from some site searchable you need to do the following few simple steps:
-
crawl the whole site with wget preserving it's original structure
-
prepare the data for Sphinx
-
index the data with Sphinx
Crawling
Just use wget -r ... -o log to crawl the whole site with wget. I've crawled www.ivinco.com:
[snikolaev@r27 ivinco]$ wget -r "http://www.ivinco.com" -o log
UPDATE: It appeared wget -nv -r "http://www.ivinco.com" -o log works better (just -r doesn't work sometimes, it depends on wget version etc.)
Preparing data for Sphinx
Any search result usually consists of at least 2 main things: snippet and link to the original document. Now that you have crawled the whole site and have all the contents it's not a problem to make snippets, you can just use Sphinx' function BuildExcerpts() to do this, but the thing you also need is a map between a document and it's original url. wget doesn't generate such map so you need to do it yourself. You should have file 'log' after the previous step. There you can find things like:
...
--05:21:14--  /feed/
           => `www.ivinco.com/feed/index.html'
...
This is the map you need, you just need to normalize it a bit:
perl -i -pe 'undef $/; s/\n+\s+=\>\s+/=>/smg' log
Now you have:
...
--05:21:14--  /feed/=>`www.ivinco.com/feed/index.html'
...
Leave only needed lines containing '=>' and Replace '=>' with a space.
[snikolaev@r27 ivinco]$ grep "=>" log|awk '{print $2}'|sed 's/=>/ /g' > map
Now you should have the following in 'map':
[snikolaev@r27 ivinco]$ head -5 map
`www.ivinco.com/index.html'
/robots.txt `www.ivinco.com/robots.txt'
/feed/ `www.ivinco.com/feed/index.html'
/xmlrpc.php `www.ivinco.com/xmlrpc.php'
/wp-content/themes/ivincowp/style.css `www.ivinco.com/wp-content/themes/ivincowp/style.css'
Sometimes the above might not work due to different version of wget etc. and you need to use some other commands to normalize, e.g.
cat log|grep "\->"|awk '{print $3 " " $6}'|sed 's/URL://g'|sed 's/"//g' > map
it's enough. You also have all files crawled by wget in www.ivinco.com:
[snikolaev@r27 ivinco]$ ls www.ivinco.com/
blog  contact-us  favicon.ico  feed  index.html  robots.txt  search  services  software  wp-content  wp-includes  xmlrpc.php  xmlrpc.php?rsd
Since you don't want Sphinx to index css/js/image etc. files you might want to filter this stuff. You can use script like this:
[snikolaev@r27 ivinco]$ cat prepare.sh
for n in `find ./ -type f|grep -v ".gif\|.jpg\|.png\|\.zip\|.css\|.js\|.ico\|.xml\|robots.txt\|xmlrpc.php\|feed"|grep "www.ivinco.com"|sed 's/^\(.\)\{2\}//g'`; do echo -n `grep $n map|awk '{print $1}'|sort -n|uniq`; echo -en "\t"; readlink -f $n; done;
This script will also output crawled documents full paths (with readlink -f) and will concatenate it with the original links from the 'map' file built earlier. As a result you will have:
[snikolaev@r27 ivinco]$ bash prepare.sh |head -5
/search/	/home/snikolaev/ivinco/www.ivinco.com/search/index.html
/services/custom-full-text-search-solutions/	/home/snikolaev/ivinco/www.ivinco.com/services/custom-full-text-search-solutions/index.html
/services/	/home/snikolaev/ivinco/www.ivinco.com/services/index.html
/services/performance-audit/	/home/snikolaev/ivinco/www.ivinco.com/services/performance-audit/index.html
/contact-us/careers/	/home/snikolaev/ivinco/www.ivinco.com/contact-us/careers/index.html
Save it to /tmp/data and you're done with preparing data for Sphinx
Indexing
Loading data from /tmp/data to mysql is very simple:
mysql> create database se;
Query OK, 1 row affected (0.01 sec)
mysql> use se;
Database changed
mysql> create table data (id int primary key auto_increment, url varchar(1024), path varchar(1024));
Query OK, 0 rows affected (0.01 sec)
mysql> load data infile '/tmp/data' into table data (url, path);
Query OK, 93 rows affected (0.00 sec)
Records: 93  Deleted: 0  Skipped: 0  Warnings: 0
Now you have the following in mysql:
mysql> select * from data limit 5;
+----+-------------------------------------------------------------------+---------------------------------------------------------------------------------------------+
| id | url                                                               | path                                                                                        |
+----+-------------------------------------------------------------------+---------------------------------------------------------------------------------------------+
|  1 | /search/                                     | /home/snikolaev/ivinco/www.ivinco.com/search/index.html                                     |
|  2 | /services/custom-full-text-search-solutions/ | /home/snikolaev/ivinco/www.ivinco.com/services/custom-full-text-search-solutions/index.html |
|  3 | /services/                                   | /home/snikolaev/ivinco/www.ivinco.com/services/index.html                                   |
|  4 | /services/performance-audit/                 | /home/snikolaev/ivinco/www.ivinco.com/services/performance-audit/index.html                 |
|  5 | /contact-us/careers/                         | /home/snikolaev/ivinco/www.ivinco.com/contact-us/careers/index.html                         |
+----+-------------------------------------------------------------------+---------------------------------------------------------------------------------------------+
5 rows in set (0.00 sec)
Use the following sphinx config to index the data:
source se
{
    type = mysql
    sql_host = localhost
    sql_user = root
    sql_pass =
    sql_db = se
    sql_query = select id, url, path from data
    sql_file_field  = path
    sql_query_info = select * from data where id=$id
}

index se
{
    path = idx
    source = se
    html_strip = 1
}

searchd
{
    listen = 9306:mysql41
    log = sphinx.log
    pid_file = sphinx.pid
}
Note that sql_file_field is used to tell Sphinx where to find the files containing data to index, Sphinx will do the rest: it will read the files itself and index the data, just give him the path.
Index the data:
Sphinx 1.11-id64-dev (r2650)
Copyright (c) 2001-2011, Andrew Aksyonoff
Copyright (c) 2008-2011, Sphinx Technologies Inc (http://sphinxsearch.com)

using config file 'sphinx_se.conf'...
indexing index 'se'...
WARNING: collect_hits: mem_limit=0 kb too low, increasing to 24576 kb
collected 58 docs, 0.3 MB
sorted 0.0 Mhits, 100.0% done
total 58 docs, 330606 bytes
total 0.047 sec, 7017149 bytes/sec, 1231.05 docs/sec
total 60 reads, 0.000 sec, 17.3 kb/call avg, 0.0 msec/call avg
total 6 writes, 0.000 sec, 51.1 kb/call avg, 0.1 msec/call avg
Voila! The data is searchable now, you can use it with any method (any api, sphinxql etc.), I used 'search' tool and query 'happen with some latency' which should find me the following document /blog/sphinx-replication/. It works:
[snikolaev@r27 ~]$ ~/bin/search -c sphinx_se.conf -a "happen with some latency"
Sphinx 1.11-id64-dev (r2650)
Copyright (c) 2001-2011, Andrew Aksyonoff
Copyright (c) 2008-2011, Sphinx Technologies Inc (http://sphinxsearch.com)

using config file 'sphinx_se.conf'...
index 'se': query 'happen with some latency ': returned 1 matches of 1 total in 0.000 sec

displaying matches:
1. document=43, weight=4681
	id=43
	url=/blog/sphinx-replication/
	path=/home/snikolaev/ivinco/www.ivinco.com/blog/sphinx-replication/index.html

words:
1. 'happen': 1 documents, 1 hits
2. 'with': 26 documents, 86 hits
3. 'some': 10 documents, 29 hits
4. 'latency': 1 documents, 2 hits
Now you know how to delegate things to existing tools to build a simple search engine: wget can crawl the web, Sphinx can read the crawled data and allow you to search in it. Of course the above algorithm isn't useful for any serious production use as is, this is just a PoC, but if you make an effort you can make something good of it.
Need help with search infrastructure? Talk to our engineering team — we've built and maintained search systems for over 15 years.
Frequently Asked Questions
Can wget be used to crawl a site for Sphinx indexing in production?
wget works well as a proof-of-concept crawler and for small internal sites, but it lacks JavaScript rendering and dynamic content handling. For production search systems, use dedicated crawlers or feed data directly from the database via sql_query. For simple static sites under a few thousand pages, the wget approach is fully viable.
What is the sql_file_field directive in Sphinx?
sql_file_field tells Sphinx to treat a database column as a file path rather than inline content. Sphinx reads each file at that path and indexes its text directly. This lets you store file references in MySQL and have Sphinx handle all the reading — useful when the actual documents live on disk after crawling.
How do I prevent Sphinx from indexing CSS, JS, and image files during a wget crawl?
Use a shell filter before loading data into MySQL. The prepare.sh script in this post uses grep -v ".gif\|.jpg\|.png\|\.zip\|.css\|.js\|.ico" to exclude non-text files from the URL/path map. Only HTML files get loaded into the data table, so Sphinx only indexes actual page content.
How does the URL-to-file mapping work in this wget setup?
wget's -o log flag writes a log containing lines like URL => local/path. A Perl one-liner and grep/awk/sed chain normalizes those lines into a tab-separated map of original URL and local file path. That map gets loaded into MySQL so each Sphinx document carries its source URL for use in search result links.
Can Sphinx strip HTML tags when indexing crawled pages?
Yes. Setting html_strip = 1 in the Sphinx index configuration tells the indexer to strip all HTML tags before indexing, so only visible text content is indexed. This avoids noise from markup, scripts embedded in HTML, and navigation boilerplate — improving search relevance significantly.
Related Reading
Related posts
Massive Indexing with Sphinx
Imagine the following situation: multiple Sphinx daemons are serving huge amount of data running on numerous hardware servers.
Sphinx: building 1M docs index having no one real doc
Just want to share an interesting trick on how to easily index something with Sphinx without need of populating database with a lot of data or doing smth...
Correct ordering of search result set using Sphinx
**Once you get results from Sphinx, it is important to maintain the way they are ordered. The typical search process used by Sphinx looks like the following:**